~ $ whoami
Imran Nazir
AI Applied Engineer II · QuillBot (Learneo)
I build the infrastructure that LLMs run on at scale.
Civil Engineering grad → self-taught → ML systems engineer. Serving 50M+ users.
LLM Inference Stack
production topology1,240 req/sImran·designs & operates this stack
about
I studied Civil Engineering at BIT Sindri, Dhanbad — graduating with an 8.99 CGPA in 2023. While most of my classmates went into construction, I was in my dorm room learning to code. No CS degree, no bootcamp — just curiosity and an obsession with building things that work.
I taught myself software engineering, data engineering, and then ML infrastructure from the ground up. That journey took me from a Full-Stack intern to a Data Engineer at Episource (acquired by Optum), and eventually to building production ML systems at Optum (UnitedHealth Group) for 3+ years — where I also managed networking for both dev and prod Kubernetes clusters, including firewall security, VPC configuration, and compliance policies.
Today I'm an AI Applied Engineer II at QuillBot, where I own the LLM serving infrastructure for 50M+ users. I work across the full inference stack — from model optimization (LoRA, QLoRA, quantization) to serving layers (vLLM, SGLang, Triton) to orchestration on Kubernetes. I shipped Rengoku, a production Kubernetes sidecar that handles async LLM inference at 5,000+ pages per batch.
I also write. My articles cover GPU inference internals, connection-level overload protection on Kubernetes, and capacity-aware LLM serving. I believe in sharing what I learn in the open.
50M+
users served
5K+
pages / batch
5 yrs
in ML systems
work experience
QuillBot (Learneo)
currentAI Applied Engineer II
Sep 2026 – Present
Remote · Bangalore
- ›Building and maintaining LLM serving infrastructure for 50M+ users
- ›Owning model deployment, versioning, monitoring, and rollback pipelines
- ›Stack: vLLM, Kubernetes, Python, MLflow
Optum (UnitedHealth Group)
MLOps and Data Platform Engineer
Jul 2023 – Sep 2026
Mumbai, India
- ›Built Rengoku — a production Kubernetes sidecar for async LLM inference (SQS → Qwen 2.5B → S3), achieving 5,000+ pages/batch via SOLID principles and dependency injection
- ›Led migration of model serving to AWS SageMaker Async via Terraform IaC; designed CI/CD pipelines with GitHub Actions
- ›Architected data pipelines with Kafka, DynamoDB, and Snowflake; led MLOps automation testing to improve end-to-end model stability
Episource → Optum
Data Engineer Intern
Jan 2022 – Jun 2023
Remote
- ›Optimised memory load in Airflow DAGs for complex multi-step pipeline orchestration
- ›Built Docker microservice architecture with AppWrite; integrated external APIs into No-Code apps
- ›Implemented access control using Casbin and OSO middleware
B.Tech Civil Engineering · BIT Sindri, Dhanbad
CGPA 8.99 · 2019–2023
projects
Rengoku
Production-grade Kubernetes sidecar acting as async middleware between AWS SQS and a self-hosted LLM inference container (Qwen 2.5B). Handles the complete async pipeline — SQS polling, inference invocation, S3 result upload, SNS/SQS notifications, and auto pod termination when the queue drains.
- ✓5,000+ pages per batch in production
- ✓SOLID principles + dependency injection
- ✓Cloud-agnostic via subclassing
Production-grade RAG system using LangChain for orchestration and a vector database for semantic retrieval. Implements LangGraph-based stateful multi-step reasoning with tool invocation. Hybrid retrieval (semantic + keyword) deployed as a FastAPI service with request batching and response caching.
- ✓+40% response relevance over baseline
- ✓Stateful multi-step reasoning via LangGraph
- ✓FastAPI service with batching + caching
Production-style Medallion Architecture on Databricks — Bronze → Silver → Gold layers with Auto Loader for incremental ingestion, Delta Live Tables for pipeline orchestration, and Unity Catalog for fine-grained governance. Spark execution tuned with AQE, partition pruning, and predicate pushdown.
- ✓AQE + partition pruning optimisations
- ✓Delta Live Tables for declarative pipelines
- ✓Unity Catalog governance layer
open source
Contributing upstream to the libraries I serve models with
writing
GPU inference internals · LLM serving at scale · Kubernetes · ML systems
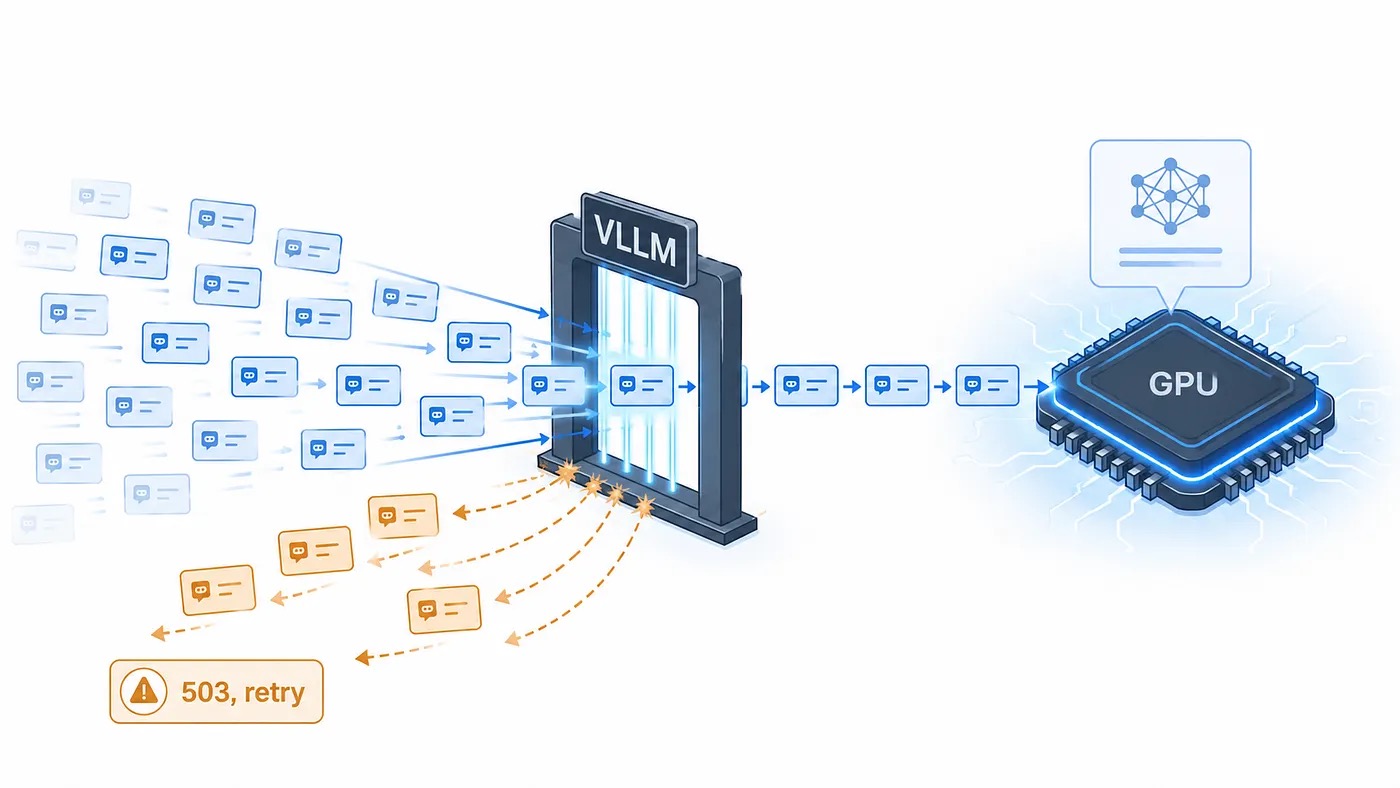
Serving LLMs Through the GPU Drought: Capacity-Aware Inference with Automatic Instance-Type Fallback
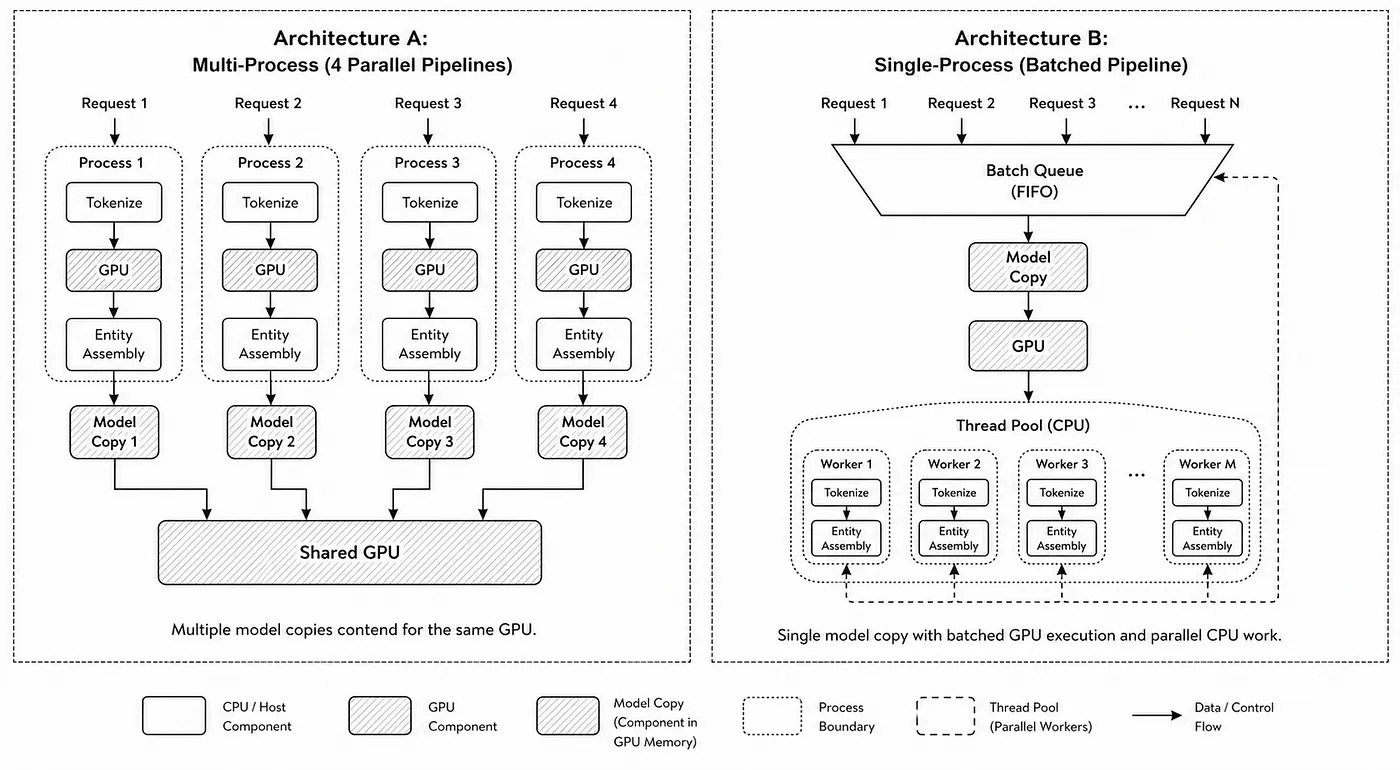
Serving Large Language Models on Kubernetes at Scale: Connection-Level Overload Protection for GPU Inference
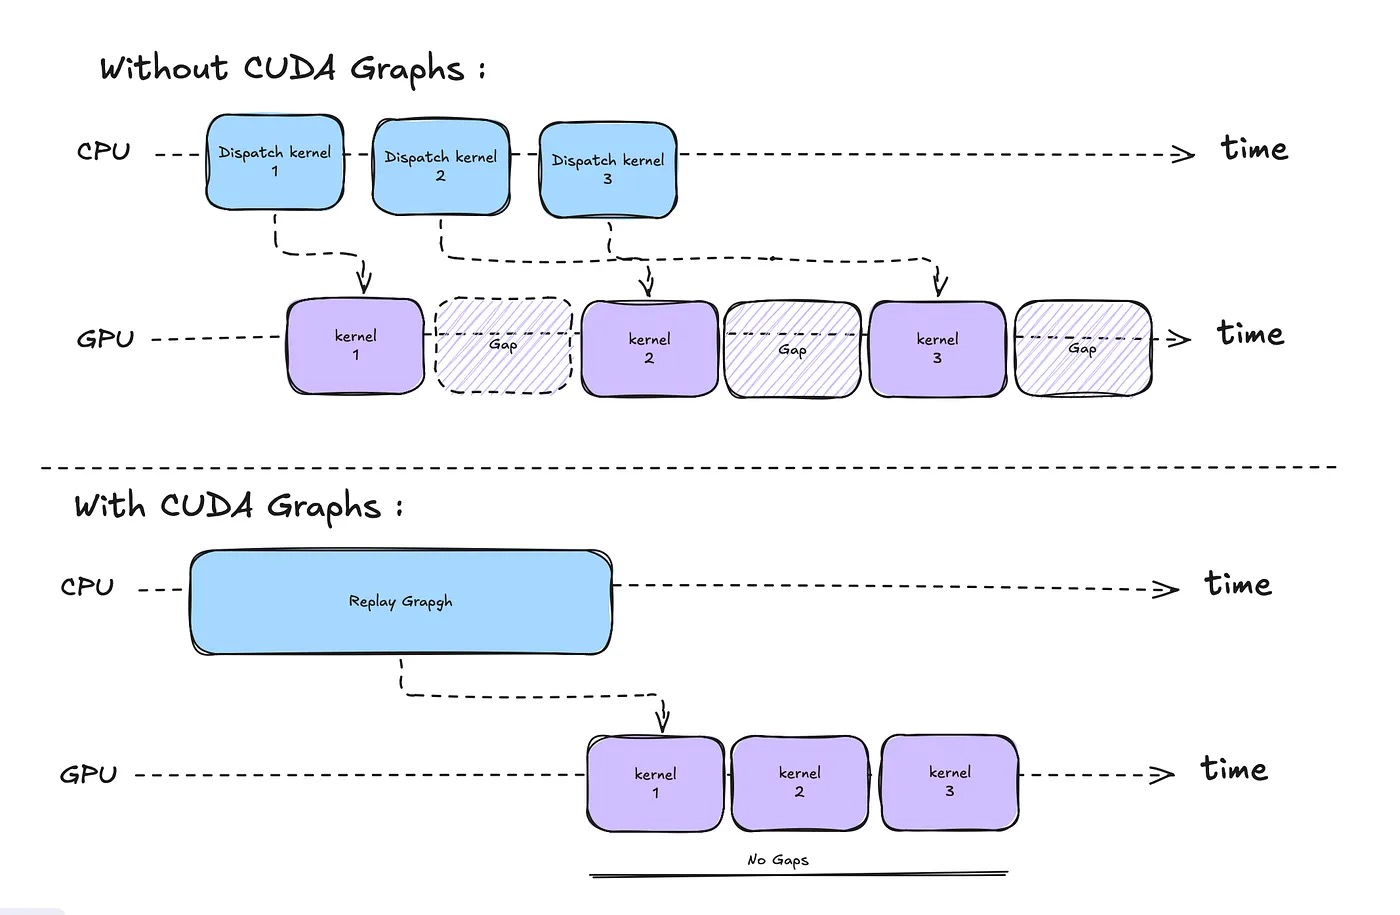
I Opened the GPU Black Box For LLM Inference. Here's What I Found!
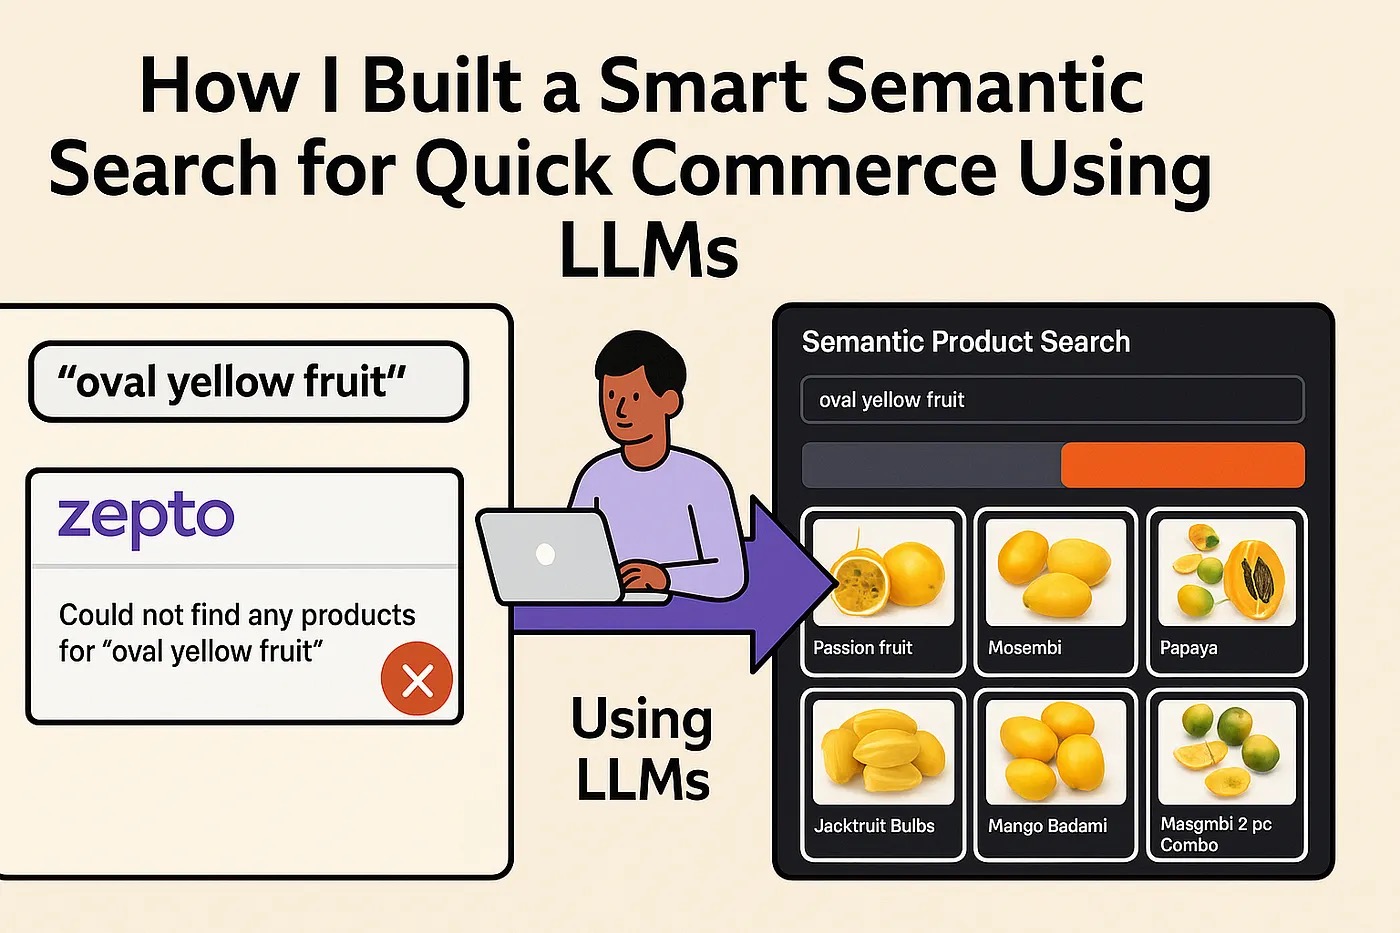
How I Built a Smart Semantic Search for Quick Commerce Using LLMs
Seamless Integration: Deploying FastAPI ML Inference Code with SageMaker BYOC + Nginx
stack
contact
Let's talk.
Open to conversations about LLM infrastructure, MLOps architecture, or GPU systems. Happy to connect on collaborations, technical writing, or speaking opportunities.
imrannaz326@gmail.com ↗